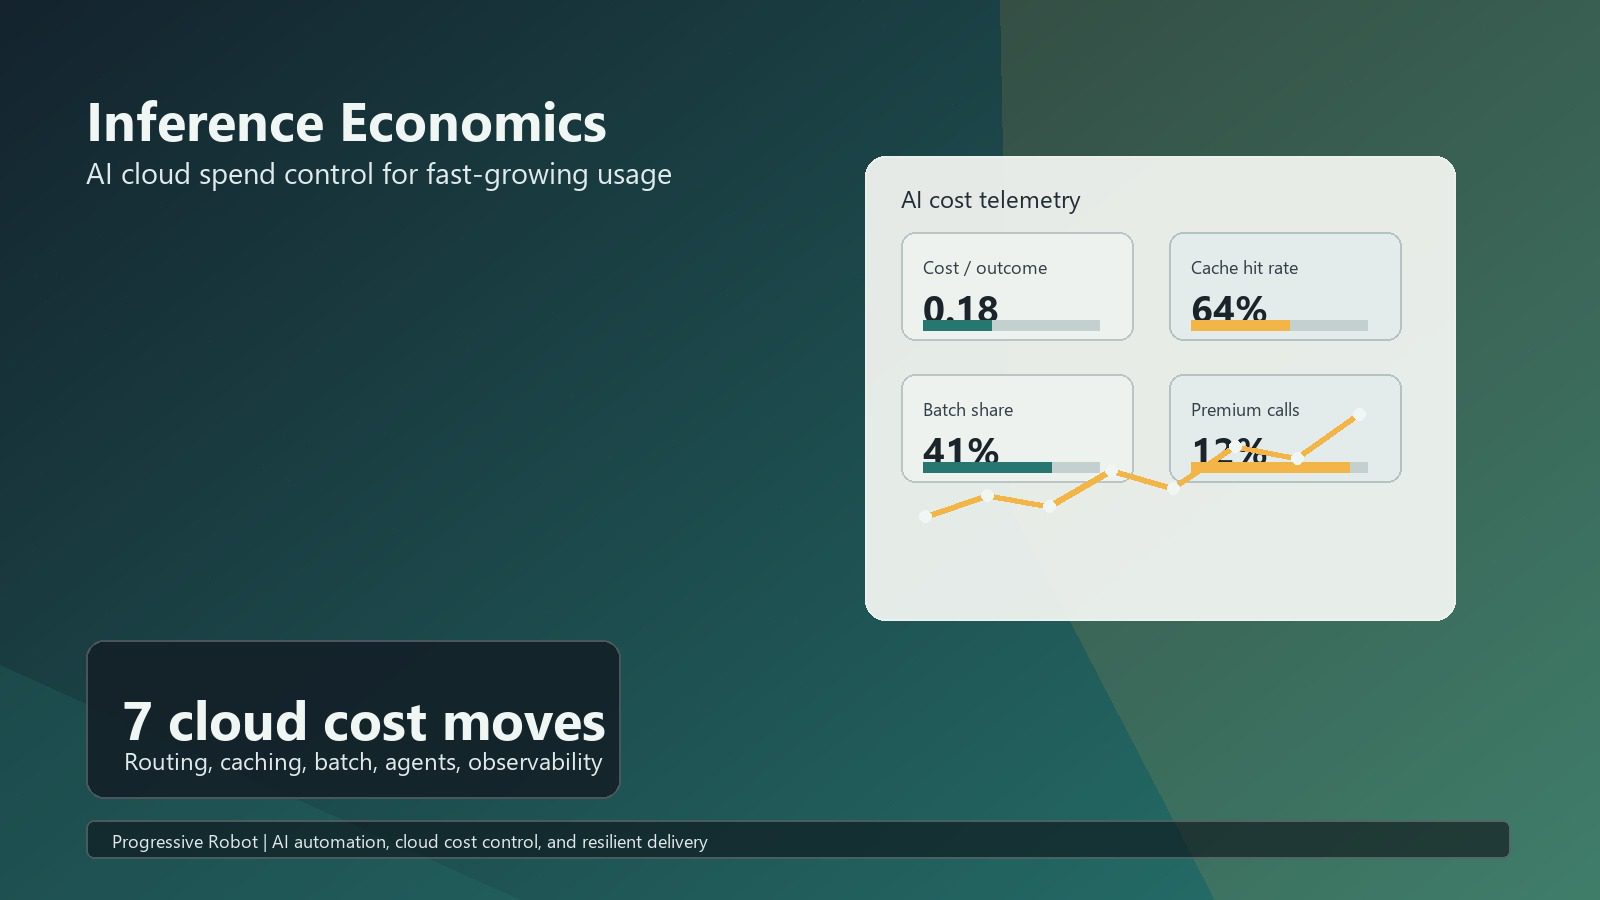
Prompt Caching

token cost control five keys ai token costs a laundry mangle with two rollers and a side handwheel

Five Keys to Controlling AI Token Costs

Model routing, semantic caching, prompt caching, reranking and response constraints are the five keys InfoWorld names for controlling AI token costs. We price each one at October 2026 list rates from Anthropic, OpenAI and Google, flag what changed in prompt caching, and work through a support-bot example that takes a modelled $62,800 monthly bill to about $7,213.
Read more
Claude Haiku 5.5 - claude haiku 5 5 launch sonnet 5 5 cache price cut a open folding hand fan standing upright

Anthropic Launches Claude Haiku 5.5 and Reduces Sonnet 5.5 Caching Costs

Anthropic has launched Claude Haiku 5.5, its cheapest and fastest small model, at up to 90% lower per-token prices than Haiku 4.5, and halved the cache read price on Sonnet 5.5. We explain the two price tiers, the tokenizer catch, the benchmarks and early customer results, the arithmetic behind the 20% Sonnet saving, the new monthly API credits for Max and Team plans, and the breaking changes developers must handle before switching.

Read more
claude fable 5 1 aixploria a claude fable 5.1 lighthouse tower

New AI Tool: Claude Fable 5.1 Has Just Landed on AIxploria

Claude Fable 5.1 is now listed on AIxploria, the AI tools directory that catalogues thousands of AI sites across more than fifty categories. The new card sits at number one on the directory’s “Latest AI” feed, carries a Gold Verified badge, is priced “Paid”, and files Anthropic’s frontier model under LLM models and SuperTools. For […]

Read more
finops for ai llm agent gpu costs a fuel gauge dial

FinOps for AI: Smart, Proven Ways to Cut LLM, Agent and GPU Costs

FinOps for AI has moved from a niche discipline to the single biggest cost-control question facing technology leaders, and most organisations are discovering it the hard way — through an invoice nobody forecast. A large language model that costs pennies per request in a pilot becomes a six-figure annual line item once it is embedded […]

Read more
ai cost governance token budgets a three rising rounded bars

AI Cost Governance: Proven Controls to Stop Costly Waste

An AI budget behaves nothing like a software budget: it moves the moment somebody writes a longer prompt, enables a more capable model or ships an agent that retries five times instead of once. This guide sets out the controls that keep inference spend predictable, covering token budgets at request, session and tenant level, a capability ladder and routing strategy that sends each task to the cheapest model that can do it, hard and soft usage limits that stop runaway agent loops, prompt caching and context discipline, tagging and unit-cost dashboards, the monthly operating cadence, and a fully worked support-copilot example.

Read more
CHAT