
AI guardrails are designed to prevent artificial intelligence systems from assisting with harmful activities, including cybercrime. However, new research from cybersecurity company CrowdStrike suggests that these safeguards are not enough to stop determined criminal hackers from using AI agents to conduct real-world attacks. Investigators identified four previously unreported threat groups that used AI models to support intrusion campaigns between May and August 2026.
The findings, reported by WIRED and detailed in CrowdStrike’s research, show how attackers are moving beyond using chatbots simply to generate code or explain technical concepts. Instead, some criminals are connecting AI models to tools and automated workflows that can carry out multiple stages of an operation.
The four groups operated in Chinese, Spanish and English, Indonesian, and Russian. Their technical capabilities varied considerably, but researchers found that even less sophisticated operators could use AI-assisted workflows to compromise targets.
The findings do not mean that AI safety systems are entirely ineffective. They show that AI guardrails cannot reliably prevent abuse when attackers can manipulate prompts, change the surrounding software or switch between different models. Organisations therefore need to combine model-level safeguards with conventional cybersecurity controls, monitoring and incident response.
1. Four Threat Groups Used AI in Real-World Attacks
CrowdStrike’s investigation examined the infrastructure used by four threat groups whose AI systems were exposed through publicly accessible web directories. This exposure gave researchers an opportunity to inspect their tools, configurations and model usage.
The groups used a mixture of commercial AI systems and open-weight models, including versions of Anthropic’s Claude and DeepSeek. Their approaches differed, but each group used AI to support operations that extended beyond ordinary question-and-answer interactions.
The Chinese-speaking and Spanish- and English-speaking operators developed more sophisticated systems for coordinating tasks. These environments could organise activities across multiple stages, allowing AI agents to assist with reconnaissance, decision-making and other parts of an intrusion.
The Indonesian- and Russian-speaking groups relied on less sophisticated approaches, yet they still managed to compromise targets. Their activity included government-related systems and private-sector organisations.
This distinction matters because the threat is not limited to highly experienced attackers with substantial resources. AI tools can reduce the amount of manual work required for certain tasks, making it easier for criminals to coordinate activity at greater speed and scale.
The investigation also illustrates why security teams must consider the entire AI-assisted workflow rather than judging risk solely by the capabilities or safety policies of an individual model.
2. Criminals Found Ways Around AI Guardrails
The central finding is that AI guardrails can be circumvented when malicious users control the instructions and software environment around a model. According to CrowdStrike, all four groups found ways to overcome safeguards intended to prevent assistance with unauthorised cyber activity.
One approach involved presenting malicious operations as legitimate penetration testing or authorised security assessments. By constructing a convincing narrative around their requests, attackers attempted to persuade models that their activities were permitted.
Some operators also placed files in an AI agent’s working directory to make their tasks appear authorised. This highlights a wider security problem: an AI system may receive information that claims an operation is legitimate without having a reliable way to verify that claim.
The attackers also used traditional prompt manipulation techniques. These included crafting instructions that anticipated refusals, reframing requests as benign activities and repeatedly pushing the models to continue when they encountered restrictions.
In one case, a Chinese-speaking operator reportedly used a tool called ClawGod to modify the runtime behaviour of Claude Code and attempt to remove a security instruction. This demonstrates that safeguards embedded in a model’s normal operating configuration may be undermined when attackers can modify the surrounding execution environment.
These findings do not establish that every model can be bypassed in every circumstance. They show that relying on AI guardrails alone is an inadequate security strategy when the user can change prompts, tools, files or execution settings.
3. AI Agents Can Coordinate More of an Attack
Traditional chatbots generally respond to individual prompts. Agentic AI systems can go further by interacting with tools, maintaining task context and coordinating multiple actions towards a goal.
This capability can be useful in legitimate settings, including software development, security testing and IT operations. It also creates additional risks when criminals connect models to infrastructure that supports unauthorised activity.
CrowdStrike observed sophisticated systems that separated supervisory and execution responsibilities. A supervisory agent could help coordinate a workflow, while other components handled specific tasks. Such architectures can reduce the need for an operator to manually direct every step.
The security implications are significant. When an AI system can call external tools or execute commands, the consequences of a mistaken decision or malicious instruction can extend beyond the model’s response. The system may interact with real accounts, services or data.
Effective AI guardrails must therefore account for what an agent can actually do, not just the language it produces. A model that refuses to describe a harmful action may still be part of an unsafe system if its connected tools have excessive permissions or lack independent enforcement.
Organisations deploying agentic AI should treat these systems as software components with access privileges, dependencies and potential failure modes. Every tool connection introduces another boundary that must be secured, tested and monitored.
4. Poor Cybersecurity Hygiene Remains a Major Weakness
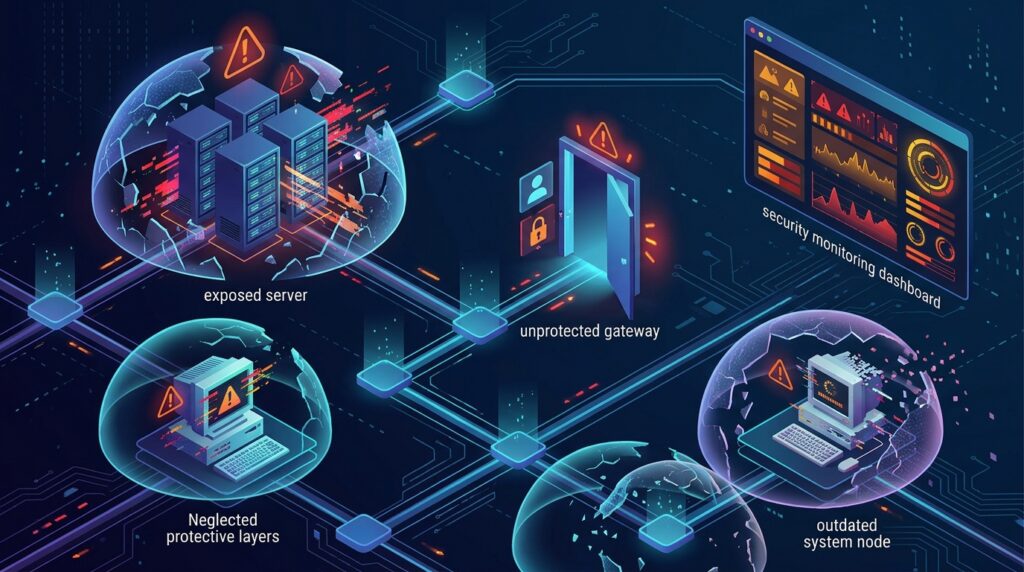
One of the most important details in the CrowdStrike findings is that the observed attacks did not depend primarily on novel software vulnerabilities. Researchers reported that attackers benefited from speed, automation and weaknesses in organisations’ existing security practices.
This is an important distinction. Public discussion of AI security can focus heavily on sophisticated model exploits, but ordinary problems such as excessive permissions, exposed services, stolen credentials and delayed remediation can still provide opportunities for attackers.
AI can help criminals work through information and coordinate repetitive activities more efficiently. It does not need to discover a completely new vulnerability to be useful to an attacker if the target already has weaknesses that can be exploited.
Organisations should therefore avoid treating AI guardrails as a replacement for fundamental cybersecurity practices. Strong authentication, timely patching, network segmentation, least-privilege access and reliable logging remain essential.
Security teams should also monitor AI agents as part of their broader attack-surface management programme. Unexpected tool use, unusual access patterns and suspicious activity involving service accounts can all warrant investigation, particularly when an agent has permission to interact with production systems.
The lesson is straightforward: sophisticated AI controls cannot compensate for preventable security gaps across an organisation’s infrastructure.
5. What Businesses Should Do to Reduce AI-Driven Cyber Risk
The findings provide practical lessons for organisations using AI assistants, coding agents and automated security tools. Rather than relying on a single safeguard, businesses should establish multiple independent controls around the model and its connected environment.
First, organisations should enforce least-privilege access. AI agents should receive only the permissions necessary for their assigned tasks, with sensitive actions requiring separate approval where appropriate. A model should not automatically inherit broad production access simply because it can perform useful work.
Second, businesses should validate authorisation outside the model. Instructions, project files and user-supplied claims should not be treated as proof that a security test is approved. Permission checks should be enforced through trusted identity and access-management systems.
Third, organisations should monitor agent activity. Logs should capture tool calls, access to sensitive resources, changes to configurations and unusual execution patterns. Security teams need sufficient visibility to reconstruct what an agent did and investigate suspicious behaviour.
Fourth, companies should test their deployments against realistic misuse scenarios. Evaluations should cover prompt manipulation, untrusted files, tool permissions, unexpected model responses and attempts to bypass operational restrictions. Testing should be repeated as models, tools and workflows change.
Finally, incident-response plans should account for AI agents as potential sources of unauthorised activity. Businesses should know how to revoke credentials, suspend agent access, isolate affected systems and preserve relevant evidence.
These measures do not guarantee that every attack will be prevented. They reduce the likelihood that a successful manipulation of an AI model will automatically become a successful compromise of business systems.
6. Why AI Guardrails Still Matter
The research should not be interpreted as proof that AI guardrails are useless. Safety measures can block many harmful requests, reduce accidental misuse and make abuse more difficult. The problem is treating them as a complete security boundary against an adversary who can adapt the surrounding environment.
AI systems operate within a broader technical context. Their behaviour depends not only on model training and refusal mechanisms but also on the prompts they receive, the tools they can access, the permissions they inherit and the checks performed by external software.
This is why layered security is particularly important for agentic AI. A model may be manipulated into attempting an unsafe action, but independent controls should still prevent it from accessing restricted resources or making unauthorised changes.
Organisations developing AI products should evaluate their systems continuously rather than relying on a one-time safety assessment. Attack techniques change, models are updated and new integrations introduce additional risks. Regular testing, monitoring and prompt-attack evaluation can help teams identify weaknesses before criminals exploit them.
For companies adopting third-party AI tools, vendor safeguards should be considered alongside deployment architecture, data handling, access controls and the organisation’s own risk requirements.
AI guardrails remain one part of responsible AI development. They are most effective when supported by enforceable permissions, secure infrastructure and clear accountability for actions taken by automated systems.
Final Thoughts
CrowdStrike’s investigation offers a clear warning: criminal hackers are already using agentic AI to support real-world intrusions, and model safety measures alone have not stopped them. The four groups examined by researchers used different levels of technical sophistication, yet all managed to overcome safeguards in their operating environments.
The most important lesson is that AI-enabled cybercrime does not always require revolutionary hacking techniques. AI can increase the speed and scale of familiar attacks, while weak security practices continue to provide opportunities for compromise.
For businesses, the appropriate response is not to abandon AI. It is to deploy it with carefully limited permissions, independent authorisation checks, comprehensive monitoring and tested incident-response procedures.
AI guardrails are valuable, but they should be treated as one layer in a broader security strategy. As AI agents become more capable and more deeply integrated into business systems, the organisations best prepared to manage the risks will be those that secure the entire workflow—not just the model.
Primary source: CrowdStrike: CrowdStrike Uncovers New Agentic AI Campaigns
Additional reporting: WIRED: AI Guardrails Aren’t Stopping Criminal Hackers
More AI coverage: explore Progressive Robot's AI Models, Tools & Releases hub — hands-on reviews, setup guides and benchmarks in one place.










