
Voice assistants make everyday tasks easier, from controlling smart-home devices to playing music and answering questions. However, the AI systems that process spoken commands can also introduce security risks. Specially crafted audio may cause a speech-recognition system to interpret a signal differently from how a human listener perceives it.
Researchers at George Mason University are investigating a technique called DivNet, designed to make these attacks harder to repeat across large numbers of devices. Developed by computer science associate professor Qiang Zeng and PhD student Ying Meng, the approach creates numerous variations of an AI model without requiring companies to train an entirely new model for every device. The research was presented at the 2026 ACM International Conference on Mobile Systems, Applications, and Services. Source: George Mason University.
The idea addresses a major challenge in deploying AI at scale: when millions of devices use the same model, a weakness discovered in one system may potentially be exploited against others. DivNet aims to reduce that shared vulnerability by introducing diversity into the models themselves.
What Is DivNet and How Does It Work?
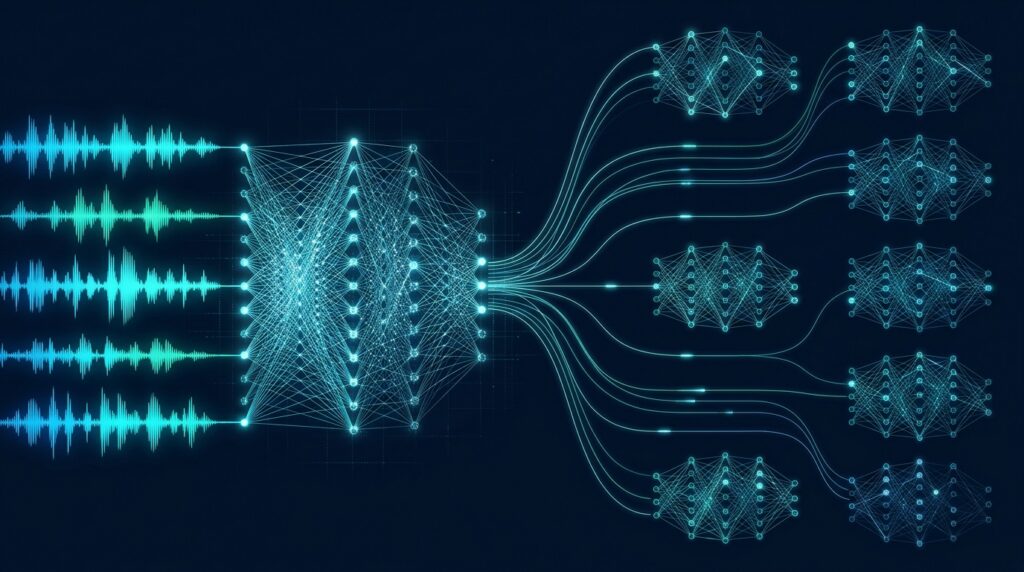
DivNet stands for a research approach described in the paper Diversified Neural Networks: Defeating Adversarial Attacks via Numerous Orthogonal Variants. Its central idea is to make AI models behave differently when confronted with malicious inputs, while retaining their ability to perform their intended tasks.
A neural network contains many numerical parameters known as weights. These values influence how the model processes input and produces an output. Some weights are important for recognising normal speech, while others may have a disproportionate influence on how the system responds to adversarial audio.
DivNet analyses the model to identify weights that can be changed with relatively little impact on ordinary speech recognition but that can influence the success of attacks. By selecting different combinations of these weights, researchers can create many model variants from a shared starting point.
This does not mean that every version is a completely independent AI system trained from scratch. Instead, DivNet seeks to reuse the expensive underlying model while generating different configurations. The intended result is a collection of systems that continue to recognise legitimate speech but do not all react identically to the same malicious recording.
That distinction is important for companies deploying AI widely. If different devices use meaningfully different model variants, attackers may find it harder to develop one recording that reliably works against every device.
Why Identical AI Models Create a Security Risk
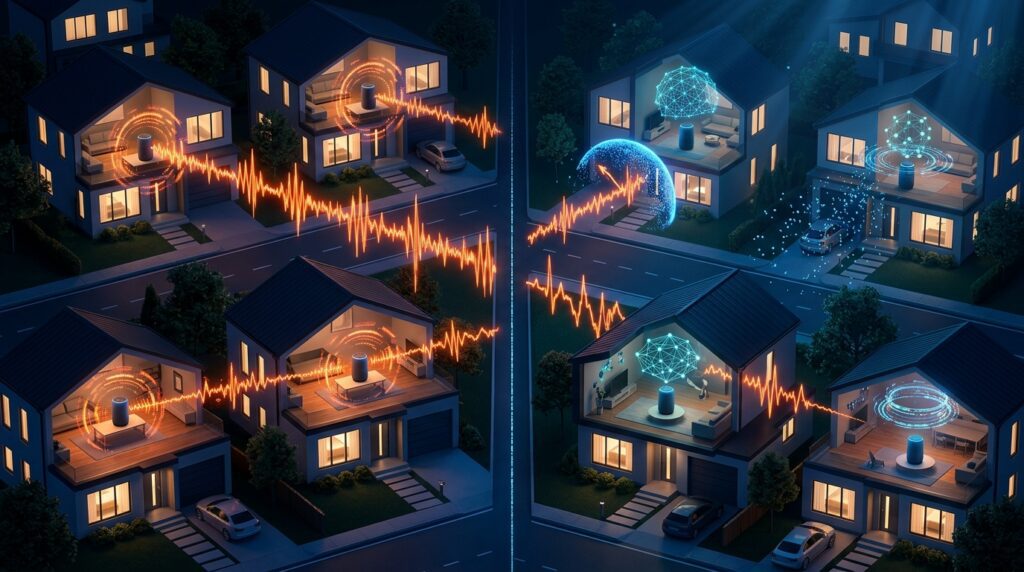
AI manufacturers often deploy the same or very similar models across large numbers of products. This approach makes economic sense: training and maintaining advanced AI systems can be expensive, and a shared model simplifies development and updates.
However, standardisation can also create a common point of failure. If an attacker discovers a malicious audio pattern that reliably fools a particular model, that recording may potentially be reused against other devices running the same vulnerable configuration.
Voice assistant security is especially important because these systems may be connected to more than entertainment features. Depending on the product and its permissions, a voice assistant may control lights, interact with connected appliances, access personal information, or initiate actions through other services. The consequences of a successful attack therefore depend on what the device is authorised to do and which additional safeguards are in place.
DivNet approaches the problem by reducing the uniformity of the underlying AI models. Rather than assuming a single defensive configuration will be equally robust everywhere, it introduces a large pool of variants that can respond differently to the same adversarial input.
Model diversity does not eliminate every security risk. It is one potential layer of defence that can complement authentication, permission controls, secure software updates, and restrictions on sensitive actions.
How DivNet Could Make Malicious Audio Attacks Harder to Repeat
The practical goal of DivNet is not simply to stop one malicious recording on one device. It is to make attacks more difficult to scale.
In a conventional scenario, an attacker might develop an adversarial audio input against a particular model and then attempt to reuse it against other devices with the same configuration. If those systems respond similarly, the attack could be easier to replicate.
With DivNet, different model variants can respond differently to that same input. An audio recording that affects one variant may fail against another, forcing an attacker to contend with a less predictable set of targets.
The research reports that testing with established speech-recognition systems substantially reduced attack success while producing only minimal reductions in normal recognition accuracy. These findings are promising, but they should be understood in the context of the systems and evaluations used in the research. They do not prove that every commercial voice assistant is now protected, or that every type of audio attack will fail.
The number of possible variants is another notable aspect of DivNet. The researchers describe a pool of possible configurations larger than the estimated number of atoms in the observable universe. This comparison communicates the enormous scale of the theoretical variant space; it does not mean that every variant has been individually tested or that every one offers identical security and recognition performance.
DivNet’s Potential Performance and Cost Advantages
One of the potential advantages of DivNet is that it seeks to avoid the expense of repeatedly training large AI models from scratch. Model training can require substantial computing resources, specialised hardware, and engineering time. A security technique that depends on full retraining for every device could be difficult to deploy economically at scale.
According to the researchers, once the initial analysis has been completed, generating a new variant takes only milliseconds. They also report that DivNet does not add processing time to speech recognition during operation. Those findings suggest the method could be attractive in settings where responsiveness and computational efficiency matter.
However, deployment costs involve more than generating model variants. Manufacturers would still need to validate the approach for their own models, test normal speech recognition across different users and environments, manage updates, and assess how the technique interacts with existing security systems.
For businesses, the key question is whether the benefits can be reproduced in real products. DivNet is an interesting research direction because it targets the economics of large-scale AI deployment: improving resilience without making every new defensive configuration as expensive as building a model from the beginning.
What DivNet Could Mean for Smart Homes and Connected Devices
Smart-home devices illustrate why improving voice assistant security matters beyond speech recognition alone. A speaker may be used to play music or provide information, but it can also serve as a control point for connected equipment.
The risk depends on the capabilities granted to the assistant. An unwanted command to play a song has different consequences from a command that changes a security setting or triggers a sensitive transaction. Devices should therefore apply stronger checks to actions with greater potential impact.
DivNet could form part of a defence strategy by making certain adversarial audio attacks less reusable across different model variants. That could help reduce the advantage an attacker gains from targeting one common model configuration.
It should not, however, replace basic security practices. Manufacturers should restrict access to sensitive operations, require additional confirmation where appropriate, maintain secure update mechanisms, and avoid granting connected devices unnecessary permissions. Users should also review which accounts and services their assistants can access.
The broader lesson is that voice assistant security needs multiple layers. DivNet addresses one specific weakness in AI model uniformity, while access control and secure system design help limit the consequences if another weakness is discovered.
Is DivNet Ready for Commercial Use?
The researchers are pursuing commercialisation and have indicated that they are seeking patent protection for the approach. That signals interest in moving the work beyond academic research, but it does not mean DivNet is already integrated into widely available consumer devices.
Before broad adoption, manufacturers would need to evaluate how the method performs with their own speech-recognition architectures, different accents, background noise, microphone characteristics, and real-world usage patterns. They would also need to assess whether the technique remains effective as attack methods evolve.
Independent testing would be valuable, particularly for determining how well the approach works against a range of adversarial audio techniques and whether its reported benefits hold across different hardware and software environments.
The next stage for DivNet will depend on such practical considerations: reliable performance, integration costs, compatibility, and evidence that the technique strengthens security without making voice assistants noticeably less useful.
Conclusion: DivNet Offers a Different Way to Defend AI Voice Assistants
DivNet addresses a specific problem created by deploying identical AI models across millions of devices. By generating many variants through selective changes to neural-network weights, the researchers aim to make malicious audio attacks less reliable from one device to another.
The reported results suggest that the approach can reduce attack success while largely preserving ordinary speech recognition in the tested systems. Its potential efficiency and enormous variant space make it an intriguing development in AI security.
Nevertheless, DivNet should be viewed as a promising research technique rather than a universal solution. Real-world adoption will depend on further evaluation, compatibility with commercial systems, and integration with established security controls.
As voice assistants become more deeply connected to homes, services, and personal accounts, defending them will require more than one clever technique. DivNet adds a useful idea to that effort: making AI systems less uniform may make certain attacks harder to reuse at scale.
Frequently Asked Questions About DivNet
What is DivNet?
DivNet is a research technique that creates numerous variants of an AI model by selectively modifying neural-network weights. Its purpose is to make adversarial attacks harder to reuse across multiple AI systems.
Who developed DivNet?
DivNet was developed by Qiang Zeng, an associate professor in George Mason University’s Department of Computer Science, and PhD student Ying Meng.
How does DivNet help protect voice assistants?
DivNet aims to make different model variants respond differently to malicious audio inputs. This can make a single attack less reliable across devices using different variants.
Does DivNet require training a new AI model for every device?
No. The approach is designed to generate variants from a shared model through selective changes rather than requiring complete retraining for every configuration.
Does DivNet eliminate voice assistant hacking?
No. DivNet targets a particular class of attacks and does not guarantee protection against every threat. It should complement other safeguards, including authentication, permission controls, and secure updates.
Is DivNet available in commercial smart speakers?
The researchers have indicated that they are pursuing commercialisation. The available research announcement does not establish that DivNet has already been deployed across mainstream consumer voice assistants.
Explore AI and Cybersecurity Solutions With Progressive Robot
AI security is becoming increasingly important as intelligent systems connect to business platforms, customer services, and physical devices. Progressive Robot helps organisations explore software development, IT solutions, cybersecurity, and AI-powered digital services.
Visit Progressive Robot to learn more about its technology services, or explore AI and automation services to see how AI solutions can support business workflows.
References
More AI coverage: explore Progressive Robot's AI Models, Tools & Releases hub — hands-on reviews, setup guides and benchmarks in one place.










